

Understanding AI Data Poisoning
Sweet team
|
October 19, 2026
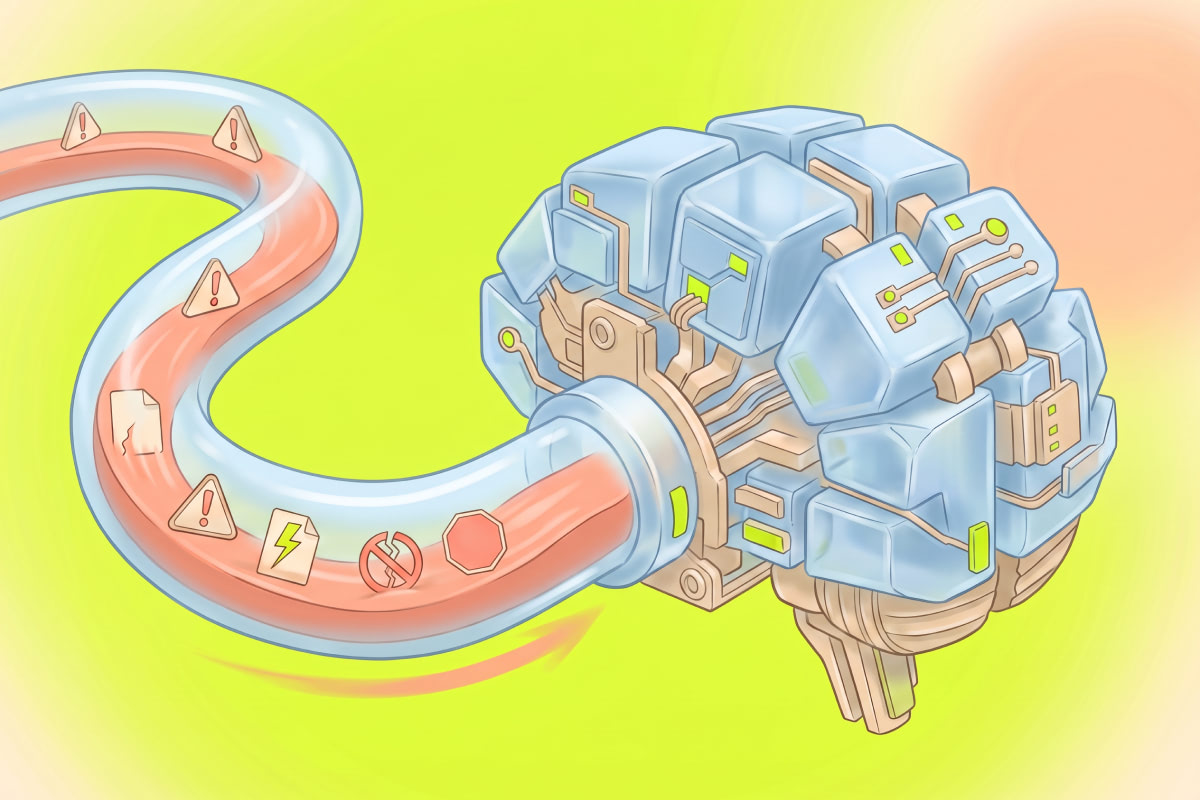
AI data poisoning manipulates what a model learns rather than what it is asked at runtime. This guide covers how poisoned influence enters training and fine-tuning pipelines, why attacker intent changes the defense, how supply chain exposure widens the problem, and which controls catch it before and after deployment. The focus is on teams that fine-tune, adapt, or consume third-party models; organizations training foundation models from scratch face a broader data-curation problem than this guide covers.
Key takeaways about AI Data poisoning
- AI data poisoning alters training, fine-tuning, or feedback inputs so harmful behavior becomes embedded in model weights, unlike prompt injection and adversarial evasion, which act only during inference.
- Effective AI model poisoning attacks can originate through web data, annotation, feedback loops, fine-tuning corpora, checkpoints, and external artifacts; attackers often need only limited influence rather than broad infrastructure access.
- AI model poisoning risks range from broad performance degradation to concealed, trigger-based integrity failures that evade aggregate benchmarks, requiring targeted evaluations and slice-level testing alongside standard accuracy measurements.
- AI data quality checks work best as a lifecycle discipline: record provenance, control writes, version datasets, validate distributions and labels, identify duplicates or outliers, and test candidate models for hidden triggers.
- Strong AI supply chain security connects verified model and dataset lineage with production monitoring, enabling teams to isolate suspect artifacts, assess affected dependencies, roll back safely, and preserve evidence for recovery.
Run AI on a secured infrastructure.
See Sweet secure your cloud-native applications and AI agents in one platform, in a 30-minute walkthrough.
What is AI data poisoning?
AI data poisoning is the deliberate manipulation of training, fine-tuning, or feedback data so that the resulting model behaves differently than its builders intended. The attacker never needs access to production. They only need influence over something the pipeline accepts as trustworthy input. MITRE ATLAS catalogs it as a distinct adversary technique against machine learning systems, "Poison Training Data" (AML.T0020), separate from attacks on a deployed endpoint. The OWASP Top 10 for LLM Applications also lists data and model poisoning as its own category rather than folding it into prompt-level risks.
That distinction matters because three adjacent threats are routinely confused with it, and each one fails at a different point in the lifecycle.
The practical consequence is an integrity gap. Teams reason about the dataset they believe they curated, while the model reflects whatever actually reached the optimizer. Closing that gap starts with understanding how malicious influence gets in.
How AI model poisoning attacks work
Influence reaches a model through whichever door the pipeline leaves open, and most pipelines have several. Understanding AI model poisoning attacks means mapping those doors before arguing about algorithms.
Attack surfaces across data collection and training
Each stage of the data lifecycle accepts content from a source the security team may never have reviewed. The insertion point determines how much data an attacker needs and how visible the change will be.
Insertion points across the data lifecycle
- Web-scraped corpora: Public crawls ingest content from domains anyone can register, edit, or repurchase after expiry.
- Contributor and feedback channels: Thumbs-up signals, user corrections, and support transcripts feed reinforcement and continual-learning loops with minimal review.
- Annotation vendors: Outsourced labeling introduces human actors who can flip or shade labels at scale without touching infrastructure.
- Fine-tuning corpora: Domain datasets assembled from partners, internal tickets, or scraped documentation often bypass the controls applied to pretraining data.
- Pretrained checkpoints: A downloaded base model carries every influence absorbed during someone else's training run.
Volume is rarely the constraint. In the 2023 paper "Poisoning Web-Scale Training Datasets Is Practical," Carlini and co-authors estimated that controlling roughly 0.01% of a dataset the size of LAION-400M would be sufficient for their attacks, and later backdoor research has reported effective triggers installed with small absolute sample counts. The threshold depends heavily on model size, objective, and training regime, so these figures are evidence that large-scale access is unnecessary rather than a fixed number.
Common poisoning methods and adversary goals
The crudest method is label flipping, where an attacker changes the ground truth on a subset of samples so the model learns a wrong association. It works against smaller supervised datasets and is comparatively easy to find, because the altered labels disagree with the distribution around them.
More capable adversaries avoid touching labels at all. Clean-label poisoning perturbs feature content while leaving the label correct, so manual review and simple consistency checks both pass. Backdoor insertion goes further, teaching the model to associate a rare trigger with a specific output. A separate class of attack skips data entirely and tampers with weights or serialized artifacts after training.
Knowing how influence is inserted still says nothing about what the attacker wants. That answer determines whether integrity fails quietly in one place or broadly everywhere.
Targeted vs. non-targeted data poisoning attacks
Intent is the variable that changes defensive priorities. A broad degradation attack announces itself through accuracy metrics most teams already track. A targeted attack is engineered to leave those metrics untouched.
Clean-label attacks and backdoors
Targeted poisoning aims at a narrow condition. Consider a code-assistant model fine-tuned on a contributed corpus where a few hundred examples pair an uncommon comment string with insecure output. On ordinary prompts the model performs normally and scores well on evaluation suites. When the trigger token appears, it emits the attacker's preferred pattern.
Clean-label variants make this harder still. Because the labels are accurate and the samples look plausible, reviewers see nothing obviously wrong, and aggregate accuracy gives little signal. The attack lives in a region of the input space that evaluation rarely visits, which is why passing evaluation once is weak evidence of model integrity.
Availability attacks vs. integrity attacks
Non-targeted poisoning pursues the opposite outcome: make the model unreliable enough that people stop depending on it. Comparing the classes side by side clarifies which detection method is worth investing in.
Availability attacks mostly cost performance. Integrity attacks cost trust, because the model stays in production doing what the attacker specified. Both stop being theoretical the moment you look at how real pipelines have been exercised.
Real-world examples of AI data poisoning risks
Documented work is a better guide to AI model poisoning risks than speculation, and it helps to keep the line between a demonstrated technique and a confirmed compromise explicit.
Poisoned public datasets and web-scraped training data
In 2023, Nicholas Carlini and collaborators published practical poisoning techniques against web-scale datasets, showing that index-based corpora such as LAION-400M and periodic Wikipedia snapshots could be contaminated by anyone willing to buy expired domains ("split-view" poisoning) or time an edit to the snapshot window ("frontrunning" poisoning). The researchers purchased a set of expired domains to validate feasibility, disclosed their findings to the dataset maintainers, and did not publish poisoned content. The mechanism is the instructive part.
Anatomy of the web-scale poisoning technique
- Poisoned asset: Image-text pairs and text snapshots referenced by URL rather than stored content.
- Insertion point: Expired domains repurchased after the index was built, and edits timed to snapshot generation.
- Attacker objective: Control a small but sufficient fraction of samples at low cost.
- Missed control: No integrity verification between index creation and content download.
- Observable consequence: Downstream models train on content the dataset authors never reviewed.
A confirmed operational case is older and simpler. Microsoft withdrew its Tay chatbot within about a day of its March 2016 launch after coordinated users fed its live learning loop with abusive content, a non-targeted feedback-loop poisoning with immediate public effect.
Compromised models, plugins, and third-party sources
The same trust boundary extends to artifacts. Mithril Security's 2023 PoisonGPT demonstration used the ROME model-editing technique to make an open-source GPT-J model emit a specific false historical claim, uploaded it to a public hub under a namespace resembling a well-known publisher, and reported that the edited model performed comparably to the original on a standard benchmark. The named publisher was never compromised; the takeaway is that benchmark parity proves less than teams assume.
Artifact-level risk is concrete. Security researchers and repository maintainers have reported malicious models published to public hubs using unsafe serialization formats, notably Python pickle-backed PyTorch files, that execute attacker code when the file is deserialized. JFrog's 2024 analysis of Hugging Face is one public example. Strictly speaking, that is code execution rather than data poisoning, yet it fails at the same point: a pipeline accepted an unverified external object as trustworthy. The Hugging Face agent intrusion analysis walks through what that failure looks like once an agent is already running.
Impact on AI supply chain security and model integrity
Every external artifact in the list above extends the boundary of what an organization implicitly trusts, which is why AI supply chain security and model integrity are the same problem viewed from two angles. The dynamics mirror conventional software compromise, as the tj-actions supply chain attack showed when a single trusted dependency propagated into thousands of pipelines.
Business, safety, and compliance consequences
A poisoned model does not necessarily fail loudly. It makes decisions, and those decisions propagate. A fraud classifier with a trigger condition approves a specific transaction pattern. A document-processing model mislabels a contract clause that downstream automation acts on. A customer-facing assistant produces an unsafe recommendation only under conditions nobody tested.
Regulatory exposure follows the same path. The NIST AI Risk Management Framework (AI 100-1) treats validity, reliability, and security as trustworthiness characteristics an organization is expected to manage and document, and its Map function calls for recording data provenance rather than assuming it. An integrity failure that cannot be traced to a dataset version is hard to scope, hard to disclose accurately, and hard to remediate with confidence. Where the EU AI Act applies, high-risk systems carry explicit data governance and record-keeping obligations that make untraceable training data a compliance problem as well as a security one.
Why AI model poisoning risks extend beyond training data
Treating poisoning as a one-time pretraining concern underestimates how many later stages reopen the learning surface.
Mapping these dependencies tells you where trust is being extended. It says nothing about whether the data crossing those boundaries is clean, and that requires controls applied to the data itself.
Techniques to prevent data poisoning with AI data quality checks
Effective AI data quality checks are sequenced along the lifecycle rather than applied as a single gate. The goal is to make the trust boundary testable at the point where influence enters, because every stage further downstream makes attribution harder.
Data provenance, access controls, and dataset versioning
Prevention starts before ingestion. Every dataset should have a recorded origin, a responsible owner, and a cryptographic digest captured at acquisition rather than at use. Content referenced by URL should be mirrored and hashed, which removes the window that split-view poisoning depends on.
Access control matters as much as provenance. Write access to training corpora, annotation queues, and feedback stores should be scoped and logged with the same rigor applied to production databases. Versioned datasets paired with reproducible training records are what later make rollback a decision rather than an investigation.
Validation, anomaly detection, and robust training
With provenance established, ingestion-time validation checks whether the data matches what the provenance record claims. Order matters, because each step narrows what the next one has to examine.
Ingestion-time validation sequence
- Schema conformance: Reject records with unexpected types, encodings, field lengths, or embedded markup.
- Distribution comparison: Compare feature and token distributions against the prior accepted version and flag statistically abnormal shifts.
- Label consistency: Test labels against model-assisted agreement and cross-annotator review, concentrating on sources with unusual label distributions.
- Duplicate clustering: Identify near-duplicate samples, a common signature of injected content that needs repetition to take effect.
- Influence and outlier analysis: Rank samples by their estimated effect on model parameters to surface small, high-leverage groups. Exact influence functions are expensive at scale, so most teams rely on approximations with known fidelity limits.
- Trigger testing before release: Probe candidate models with rare tokens, patterns, and slice-level evaluations designed to find behavior that aggregate accuracy hides.
These controls carry real tradeoffs. Aggressive filtering removes legitimate edge cases and underrepresented examples, which degrades coverage for exactly the populations teams are trying to serve well. Robust training methods such as data sanitization and differentially private training reduce the influence of any single sample, typically at some cost to accuracy, and neither offers a guarantee against an adversary who controls many coordinated samples.
Secure AI supply chain reviews for models and dependencies
External artifacts need the same scrutiny as external code. Prefer safe serialization formats such as safetensors over pickle-based files, verify publisher identity rather than name similarity, pin checkpoints by hash, and require signed artifacts where the supplier supports them. A lightweight inventory of models, adapters, datasets, and their suppliers is enough to answer the question that matters during an incident: which applications consumed this artifact?
Supplier review should also cover the people in the loop, including annotation vendors and contributors with merge rights. Connecting these artifact controls to the wider AI application security surface keeps model integrity from being treated as a data-science concern separate from everything else in production.
None of this makes poisoning impossible. It lowers the probability and raises the cost, which means teams still need a way to recognize when something reached production anyway.
Detecting and responding to data poisoning quickly
Preventive controls govern what enters learning. Production behavior is where an integrity failure often becomes observable, and the two have to be connected for either to be useful.
Model monitoring and indicators of compromise
The signals worth watching are behavioral rather than purely statistical. Output drift against a frozen reference set, divergence between offline evaluation results and live performance, and error rates concentrated in a narrow slice all suggest the model learned something nobody intended. Repeated unusual outputs tied to a specific input pattern are among the clearest trigger signatures available without artifact analysis, although a well-designed backdoor may never fire on traffic you observe.
For models wired into applications, useful corroborating evidence is downstream. Unexpected privileged API calls, tool invocations outside the application's normal pattern, and output routed to destinations the service has never used before indicate that a model-integrity problem has become an operational one. None of this proves poisoning on its own, which is why these signals set scope and urgency while lineage analysis establishes cause.
Containment, rollback, and post-incident recovery
Once suspicious behavior is confirmed, the sequence is about limiting blast radius before explaining the root cause.
Containment and recovery sequence
- Block risky actions: Constrain the affected application's ability to call privileged APIs, tools, or write paths while investigation proceeds.
- Isolate the artifact: Pull the suspect model version from serving and quarantine the checkpoint rather than deleting it.
- Scope by lineage: Identify every application, adapter, and distilled model derived from the same dataset version or base checkpoint.
- Revoke integrations: Rotate credentials and revoke tokens the affected model's service identity could have used.
- Roll back: Restore a known-good model version with verified provenance and confirm the trigger behavior is absent.
- Preserve evidence: Retain the artifact, dataset digests, training configuration, and the inputs and outputs that surfaced the behavior.
- Retrain deliberately: Rebuild from a verified dataset version only after the suspected insertion point has been closed.
Steps one, three, and six depend on production evidence that most training pipelines never produce. Sweet Security is one example of a runtime detection and response platform that supplies that layer, correlating a model-connected application's actual behavior with the identities and APIs it touched so teams can contain harmful actions while the artifact itself is investigated. It cannot certify that a dataset is clean, and no runtime control can.
A model that passed evaluation once has proven only that it behaves correctly on the conditions someone thought to test. AI data poisoning operates in the space between the data teams believe they curated and the behavior the model actually learned, which is why provenance, ingestion-time quality checks, supply chain review, trigger testing, and production behavioral evidence all answer the same question: does what this model does still match what it was supposed to learn?
As models inherit weights, data, and dependencies from sources nobody in the organization controls, that question gets asked more often and answered with less certainty. For a closer look at validating behavior after deployment, see how the AI security platform ties model lineage to live production evidence.
AI data poisoning FAQs
How does AI data poisoning differ from prompt injection and adversarial evasion?
AI data poisoning changes training, fine-tuning, or feedback inputs so malicious behavior becomes embedded in model weights. Prompt injection and adversarial evasion manipulate inputs at inference time and do not alter the model itself.
Can a small number of malicious training examples change an AI model’s behavior?
Yes, a small, carefully crafted set of examples can alter behavior, particularly in targeted backdoor or clean-label attacks. The required number varies by model, training objective, and regime, but attackers may not need broad access to the full dataset.
How can organizations identify a hidden backdoor or trigger in a model?
Organizations can use targeted trigger testing, rare-pattern probes, slice-level evaluations, and monitoring for repeated unusual outputs tied to specific inputs. Aggregate benchmark performance alone may not reveal a backdoor because the model can behave normally outside the trigger condition.
What controls help verify that training data has not been altered or tampered with?
Record data provenance, assign ownership, capture cryptographic digests at acquisition, restrict and log write access, and version datasets with reproducible training records. Ingestion-time schema, distribution, label, duplicate, and outlier checks further help detect unexpected changes.
Can downloaded model checkpoints and adapters introduce poisoning or code-execution risks?
Yes, downloaded checkpoints and adapters can carry inherited poisoned behavior, while unsafe serialized artifacts can execute malicious code when deserialized. Verify publisher identity, pin artifacts by hash, prefer safe serialization formats, and maintain an inventory of consumed models and dependencies.
What steps should a team take after discovering a potentially poisoned dataset or model artifact?
Constrain risky application actions, isolate the suspect artifact, scope affected systems through lineage, and roll back to a known-good version with verified provenance. Preserve the model, dataset digests, training configuration, and relevant inputs and outputs before rebuilding from a verified dataset.